Abstract
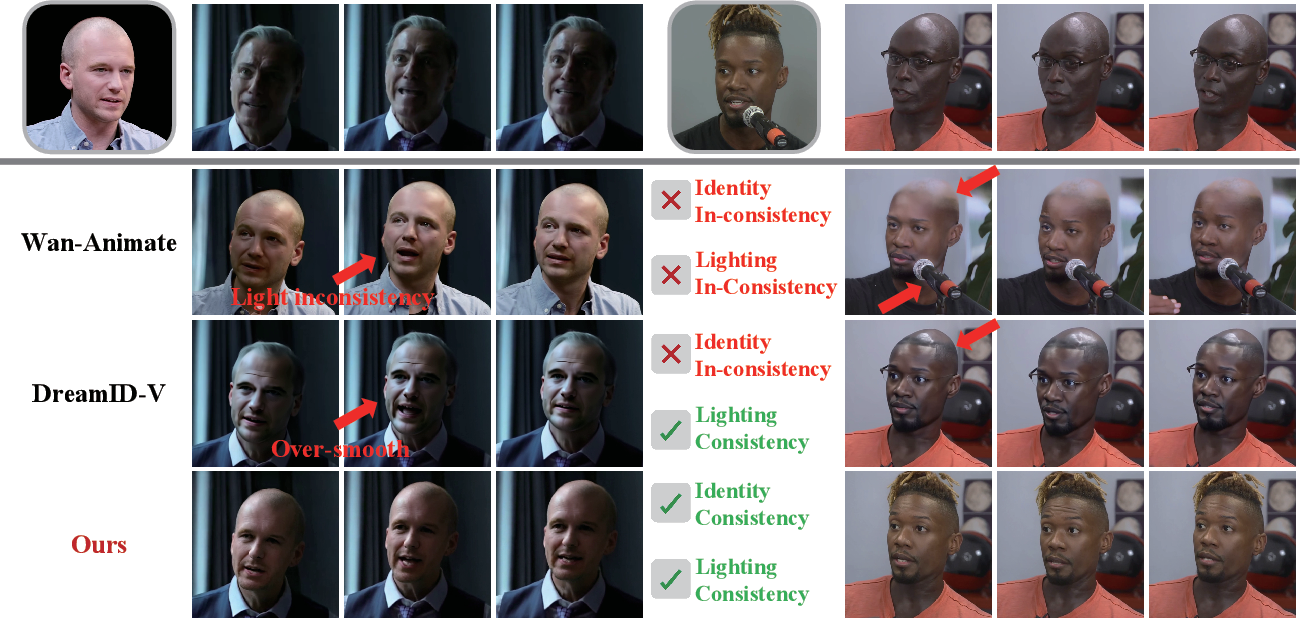
Despite yielding higher visual quality than image-to-image approaches, masked generation paradigms for video face editing fundamentally lack attribute consistency (e.g., illumination, background). We introduce LumaID, a novel framework that explicitly disentangles identity and expression representations from environmental contexts, enabling high-fidelity, fine-grained video head editing while strictly preserving these crucial attributes. At its core, LumaID employs an Omni-Disentangled Diffusion Transformer (OD-DiT) that leverages 3D proxy representations to thoroughly isolate the source and target facial features, fundamentally preventing identity leakage and illumination degradation. To further overcome the distributional drift caused by proxy estimation noise and the lack of explicit consistency supervision, we propose Consist-GRPO. This post-training reinforcement learning mechanism formulates multi-dimensional reward signals (spanning identity, expression, pose, and lighting) to continuously steer the generative process toward strict spatiotemporal alignment. Extensive evaluations demonstrate that LumaID serves as a highly competitive baseline, exhibiting strong performance over prior approaches in both attribute consistency and overall visual quality.
Framework
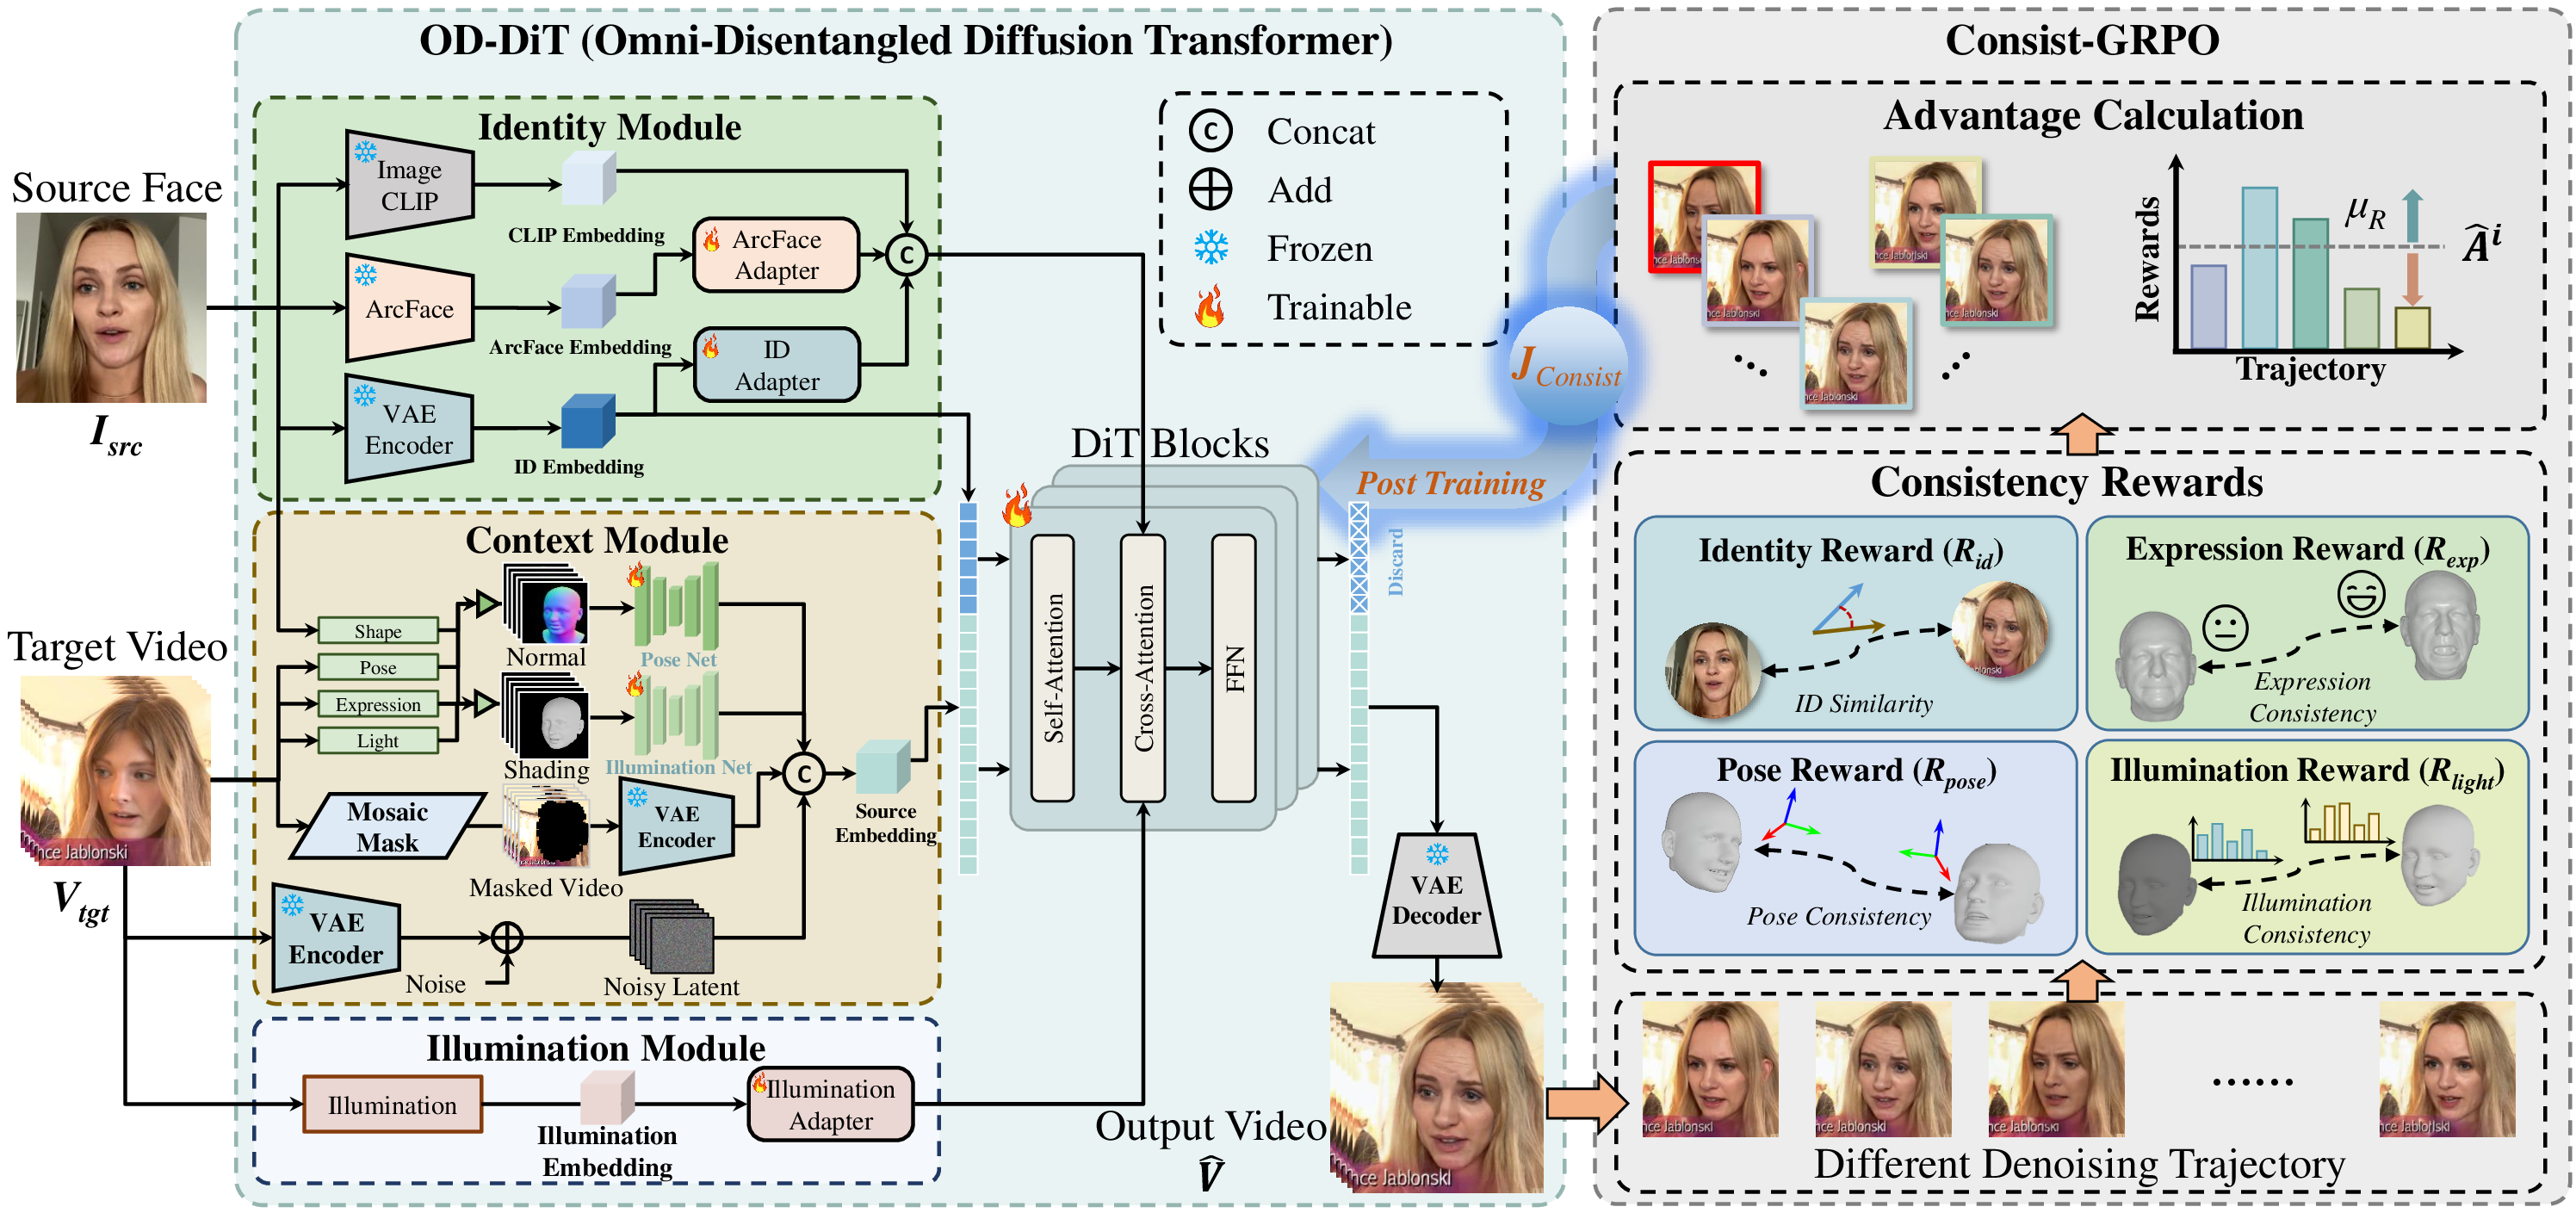
Overview of LumaID. The Omni-Disentangled Diffusion Transformer (OD-DiT) disentangles the editing process through three dedicated modules: an Identity Module that extracts source identity features via CLIP, ArcFace, and VAE embeddings; a Context Module that encodes the target video's shape, pose, expression, and lighting through 3D proxy representations; and an Illumination Module that injects the target's illumination embedding into the generation process. On top of OD-DiT, Consist-GRPO post-trains the model with multi-dimensional consistency rewards — identity, expression, pose, and illumination — computed over different denoising trajectories to steer generation toward strict spatiotemporal alignment.
BibTeX
@inproceedings{wei2026lumaid,
  title={LumaID: Harnessing Illumination-Awareness for High-Fidelity Video Head Identity Editing},
  author={Wei, Yiying and Chen, Xuanhong and Amirpour, Hadi and Timmerer, Christian},
  booktitle={Proceedings of the 34th ACM International Conference on Multimedia (MM '26)},
  year={2026}
}